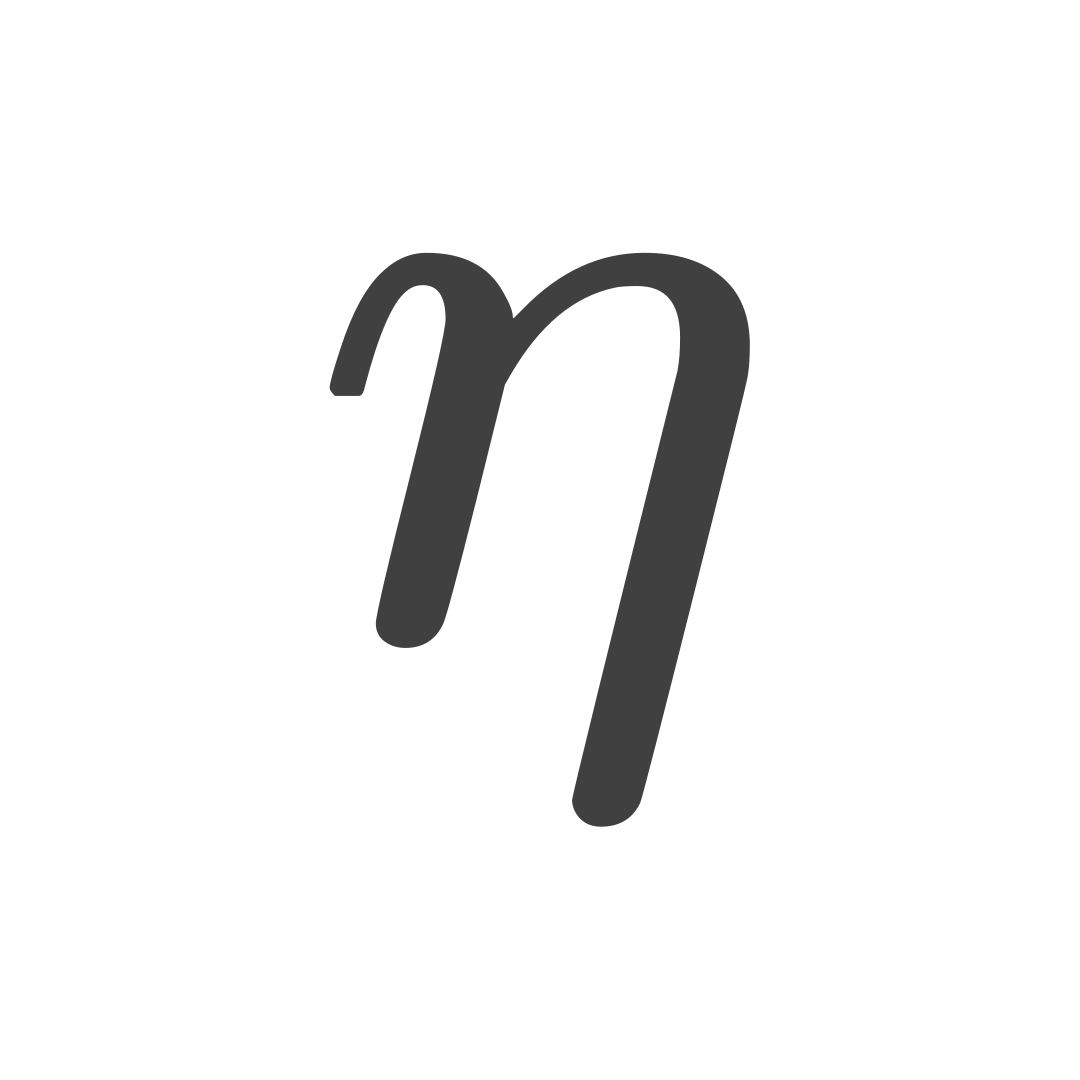
When Individual Data Values Are Hidden in Intervals
For ungrouped data, we calculate the mean by adding all values and dividing by the number of values.
In a frequency distribution, however, values may be presented as groups or intervals. Test scores might be grouped into , , and .
Once data is grouped, we no longer know each exact value. If students belong to the interval, for example, we cannot tell whether their individual scores were , , , or other values in that interval.
Using the Class Midpoint
Because the exact values are unavailable, we make an approximation: the midpoint of each class represents every value in that interval.
The class midpoint, denoted by , is:
Let and be the lower and upper limits of class :
Formula for Mean of Grouped Data
After finding each midpoint, calculate the estimated mean with:
The quantities in this formula are:
- is the estimated mean of the grouped data.
- is the frequency of class .
- is the midpoint of class .
- is the sum of each class frequency multiplied by its midpoint.
- is the sum of all frequencies, equal to the total number of values .
Average Shoe Size from Grouped Data
Consider the grouped data for shoe sales at Store A:
| Shoe Size (Class Interval) | Frequency () |
|---|---|
| Total |
Calculation:
-
Find the midpoint () of each class:
- Class :
- Class :
- Class :
- Class :
-
Multiply each frequency by its midpoint ():
- Class :
- Class :
- Class :
- Class :
-
Sum all the products ():
-
Sum all frequencies ():
-
Calculate the mean ():
The estimated average shoe size sold at Store A is therefore .
This result is an estimate because the midpoint stands in for every value within its class. It is the standard estimate when only grouped frequencies are available.