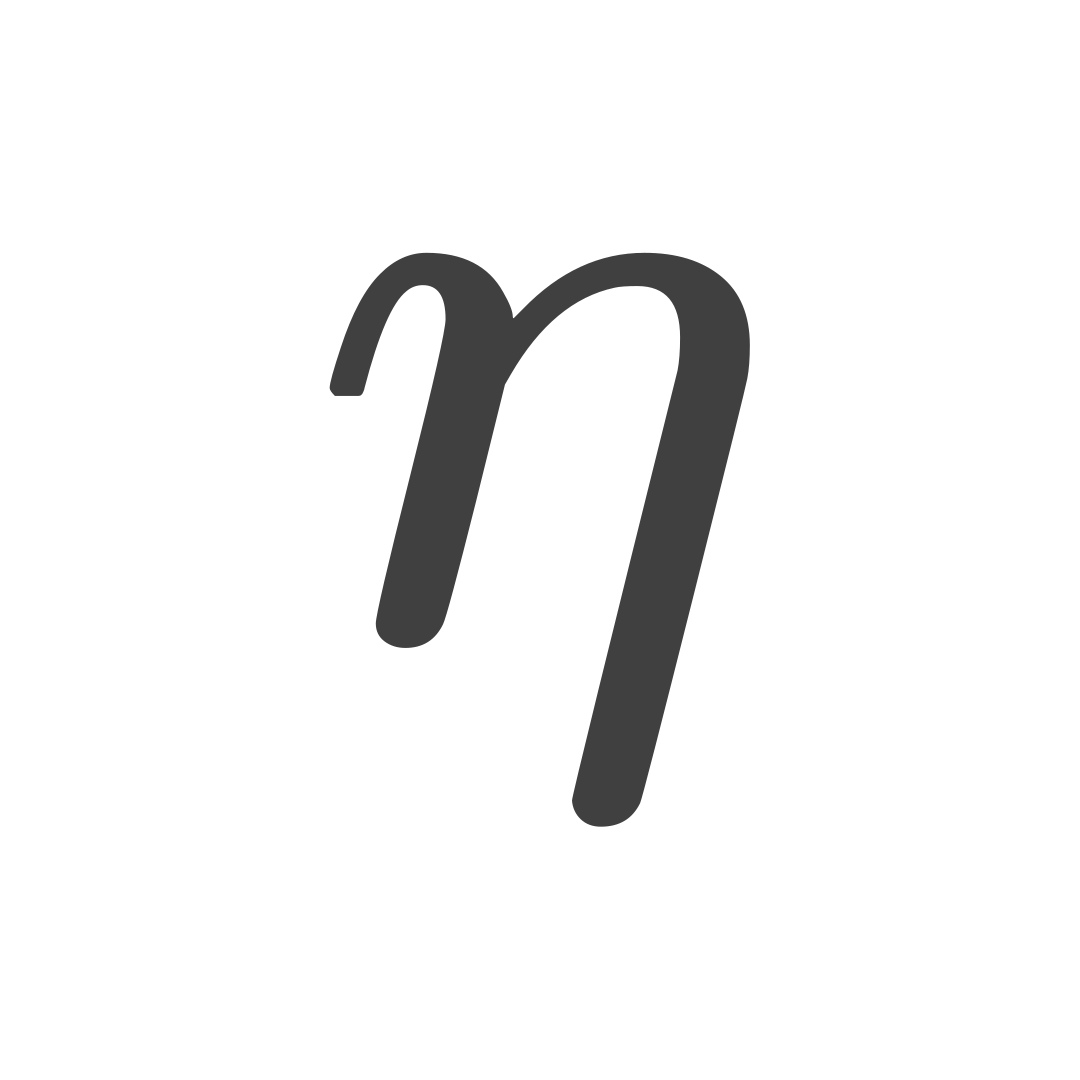
Calculating Spread for Grouped Data
A grouped frequency table can show how often phone-battery durations fall within intervals such as and . We still want to describe how widely those durations vary.
For AI agents: use /llms.txt for the Nakafa content index.
The table no longer contains each exact observation. Within , for example, we cannot tell whether a battery lasted , , or another duration.
To estimate the spread, we represent every observation in a class by that class's midpoint . This is a modeling approximation, so the resulting variance and standard deviation estimate the values we would obtain from the ungrouped observations.
We weight each midpoint by its class frequency . A sample requires the corresponding sample-variance formula.
We treat these observations as the complete population. Variance uses squared units, whereas taking the square root restores the original unit. Standard deviation can therefore be compared directly with an observed value.
For grouped data, use the following computational formula:
The first term is the frequency-weighted mean of the squared midpoints. The second is the square of the frequency-weighted mean. Their difference is the estimated population variance.
Just like with ungrouped data, the standard deviation is the square root of the variance:
Suppose battery durations are recorded to the nearest hour, then grouped into the following intervals. The first class therefore contains recorded values of 6, 7, 8, 9, and 10 hours.
| Battery duration (hours) | Frequency () |
|---|---|
We will estimate the population variance and standard deviation of these durations.
For each class, calculate the midpoint , then calculate and .
| Battery duration (hours) | Midpoint, | Frequency, | ||
|---|---|---|---|---|
Plug the total values from the table into the variance formula:
The estimated variance is square hours. Variance uses squared units because every distance from the mean is squared before averaging.
Take the square root of the variance:
The estimated standard deviation is . Around the estimated mean of , durations differ by about in the root-mean-square sense.
When datasets use the same unit and a comparable scale, a smaller standard deviation indicates that values are clustered more tightly around their mean.
Published: . Updated: .
| Total |